Solving a Real AI Engineer Take-Home Assignment Live
Recording available with Main or above.
We solve a real AI engineer take-home assignment live. The product is a small investment coaching bot that answers public-company research questions without crossing into personalized financial advice.
The flow of the session:
- Brainstorm scope and survey data sources.
- Build a CLI agent with PydanticAI and OpenAI.
- Switch from a paid market-data API to free SEC EDGAR data after the free tier blocks us.
- Clean up the pointless tests the coding agent generated and write test guidelines we actually want to follow.
- Add a small evaluation harness with scenarios and an LLM judge.
- Wrap the result as a Telegram bot.
We do every step with a coding agent. We include the prompts verbatim, so you can repeat the same steps with any agent you like.
Links
Useful resources for this workshop:
The app you will build
The final app looks like this:
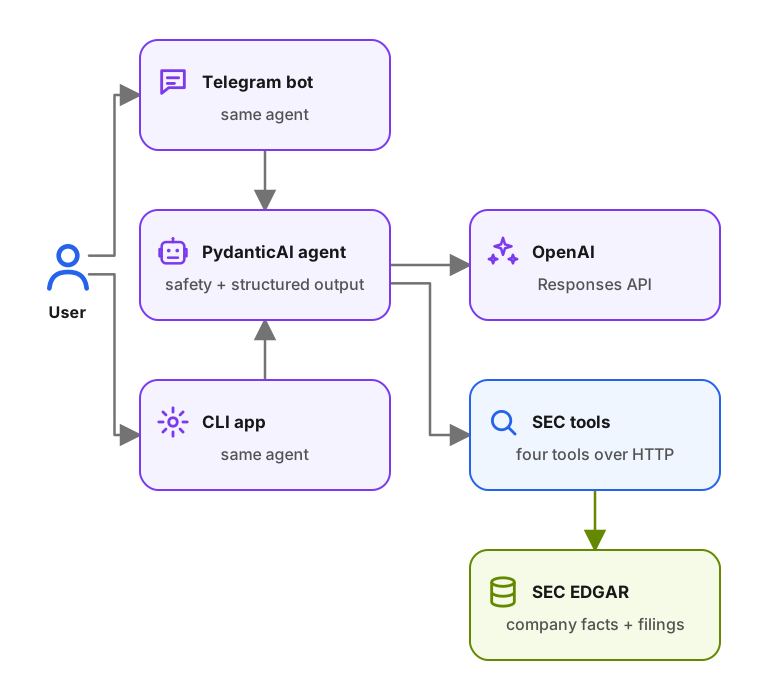
The agent has four tools, all backed by free SEC EDGAR endpoints:
search_company(query)resolves a ticker or company name to a CIK.get_financial_snapshot(ticker_or_cik)fetches recent annual revenue, profit, balance sheet, and cash facts from companyfacts XBRL data.get_latest_filings(ticker_or_cik)returns recent filing metadata and SEC URLs.get_filing_digest(ticker_or_cik, form_type)pulls the latest 10-K or 10-Q text and extracts business, revenue, risk, and MD&A snippets.
The agent's instructions set a strict safety boundary:
- no buy/sell/hold recommendations
- no position sizing
- no predictions of price direction
The agent turns a buy/sell question into an educational research brief instead.
The evaluation harness is in evals/manual/. It runs a list of
scenarios from scenarios.csv through the agent and records the full
trajectory (the sequence of tool calls the agent made). An LLM-as-judge
then scores whether the answer stayed inside the safety boundary and
answered the question.
Upgrade to Basic to access this workshop
- Full workshop overview
- Complete page list
- Step-by-step tutorial
- Cancel anytime
Tutorial pages
- Overview and setup
- Pick a task and scope the agent
- First CLI agent with PydanticAI
- Pivot from FMP to SEC EDGAR
- Cull pointless tests and write guidelines
- Write real agent and SEC tests
- Manual evaluation with scenarios and a judge
- Wrap the agent as a Telegram bot
- Deferred items and how to clean up
- Wrap-up and reflections
More from AI Shipping Labs
Jev for LLM Evaluations
In the batch and flex workshop we built an eval for the FAQ agent and scored it with an LLM judge. Here we swap that judge for Jev, a model that returns typed decisions instead of…
September 22, 2026
After the Interview: Offers and Negotiation
What happens after the interviews end: how to handle rejections without losing momentum, when to accept an offer, and how to negotiate salary with confidence.
September 16, 2026
The AI Engineering Field Guide
A data-driven guide to the AI engineer role: what the job involves, how the interview process works, and how to handle offers, based on 6,964 real job descriptions.
September 16, 2026