Build an Agent Evaluation Framework with OpenAI Batch and Flex
Event times are shown in Europe/Berlin. Sign in to use your timezone
Continue with the workshop writeup
Open the canonical pages, recording, materials, and code repo.
We take the FAQ agent from the first deployment workshop and build an evaluation framework around it. We don't change the agent, so all the new work goes into the pipeline around it. The pipeline generates synthetic student questions, runs the agent over them, and then asks an LLM judge to score the answers. We end up with a repeatable eval set that we can rerun after every change to the agent.
Two OpenAI pricing features make the eval cheaper to run. The Batch API processes a whole file of requests at about half the standard price. It returns results within 24 hours, usually within a few minutes.
Flex processing charges the same batch rate but returns results in real time, with a longer and less predictable wait. You can combine both with prompt caching. It applies automatically when requests start with the same text (the prompt prefix).
In this session we explore and don't aim for polished code. We port a working synthetic-data generator from the AI Engineering Buildcamp to this project. Then we try Batch and Flex on the same task and compare what each gives us.
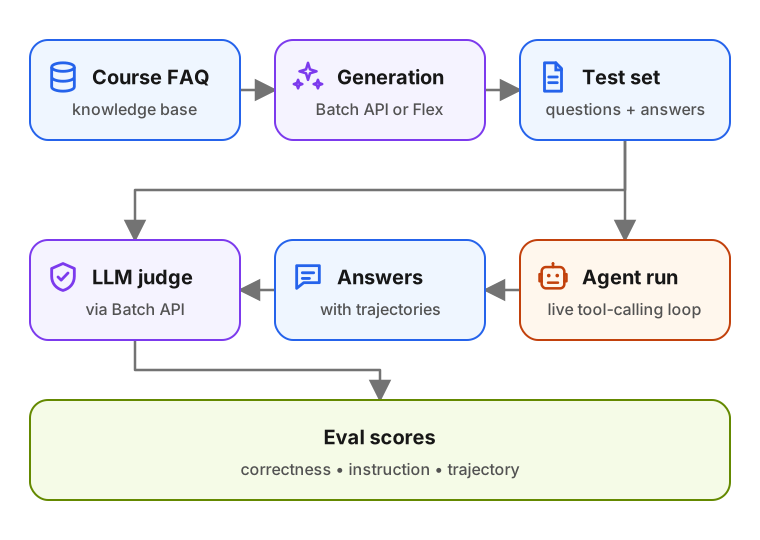
Generation and judging are batches of independent one-shot LLM calls, so both fit the Batch API. Running the agent needs live back-and-forth tool calls, so we keep it on the standard endpoint.
I used Claude Code with Opus for most of the coding. I dictated most prompts, and the agent both wrote and tested the scripts. The code is exploratory, and I point out places to refactor for a cleaner version.
Links
Resources used here:
- End-to-End Agent Deployment - the FAQ agent we evaluate.
- AI Engineering Buildcamp synthetic eval code - the working version we port from.
- OpenAI Batch API guide - the docs for the batch endpoint.
- OpenAI Flex processing guide - the docs for the flex tier.
- OpenAI prompt caching - how prompt caching applies across Batch and Flex.
Hosted by
Alexey Grigorev
Chief Agent Officer at AI Shipping Labs
Software engineer and machine learning practitioner with 15+ years of experience building production ML systems. I focus on practical, production-grade ML and AI systems, from early prototypes to reliable systems in production.
I'm the founder of DataTalks.Club, a free community that connects tens of thousands of practitioners worldwide, and the creator of the Zoomcamp series, free, code-first programs that have reached 100,000+ learners globally.
At AI Shipping Labs, I'm building the kind of environment that would have accelerated my own career growth. After years of teaching at scale, I wanted something more focused: a space for action-oriented builders who want to turn AI ideas into real projects. The community gives members the structure, accountability, and peer support to ship practical AI products consistently, even alongside their main jobs.
More from AI Shipping Labs
AI Dev Tools Office Hours — Session 4
Open office hours to discuss AI dev tools, workflows, and shipping AI products. Bring your questions.
September 29, 2026
Jev for LLM Evaluations
In the batch and flex workshop we built an eval for the FAQ agent and scored it with an LLM judge. Here we swap that judge for Jev, a model that returns typed decisions instead of…
September 22, 2026
AI Engineering Buildcamp: From RAG to Agents
A hands-on course on building production AI applications with large language models: retrieval-augmented generation (RAG), structured output, AI agents, testing, monitoring, and e…